/* Single-page scrollable site for Katyani Singh */
const { useState, useEffect, useRef } = React;

const SECTIONS = [
{ id: 'about', label: 'About' },
{ id: 'research', label: 'Research' },
{ id: 'projects', label: 'Projects' },
{ id: 'publications', label: 'Publications' },
{ id: 'ongoing', label: 'Ongoing' },
{ id: 'industry', label: 'Industry' },
{ id: 'teaching', label: 'Teaching' },
{ id: 'contact', label: 'Contact' }];


function StickyNav({ active }) {
  return (
    <nav className="sp-nav">
      <a className="sp-brand" href="#about">
        <span className="first">Katyani</span> Singh
      </a>
      <div className="sp-nav-links">
        {SECTIONS.map((s) =>
        <a key={s.id} href={`#${s.id}`} className={active === s.id ? 'active' : ''}>
            {s.label}
          </a>
        )}
      </div>
    </nav>);

}

function ExpandCard({ summary, children, defaultOpen = false }) {
  const [open, setOpen] = useState(defaultOpen);
  const ref = useRef(null);
  const opened = useRef(defaultOpen);
  useEffect(() => {
    if (!ref.current || opened.current) return;
    const io = new IntersectionObserver(entries => {
      entries.forEach(e => {
        if (e.isIntersecting && !opened.current) {
          opened.current = true;
          setOpen(true);
          io.disconnect();
        }
      });
    }, { threshold: 0.35, rootMargin: '0px 0px -10% 0px' });
    io.observe(ref.current);
    return () => io.disconnect();
  }, []);
  return (
    <div ref={ref} className={`xcard ${open ? 'open' : ''}`}>
      <button className="xcard-head" onClick={() => setOpen(!open)} aria-expanded={open}>
        <div className="xcard-summary">{summary}</div>
        <div className="xcard-toggle">{open ? '−' : '+'}</div>
      </button>
      {open && <div className="xcard-body">{children}</div>}
    </div>);

}

function useActiveSection() {
  const [active, setActive] = useState('about');
  useEffect(() => {
    const obs = new IntersectionObserver(
      (entries) => {
        entries.forEach((e) => {if (e.isIntersecting) setActive(e.target.id);});
      },
      { rootMargin: '-40% 0px -55% 0px', threshold: 0 }
    );
    SECTIONS.forEach((s) => {
      const el = document.getElementById(s.id);
      if (el) obs.observe(el);
    });
    return () => obs.disconnect();
  }, []);
  return active;
}

/* ============ ABOUT ============ */
function AboutSection() {
  return (
    <section id="about" className="sp-section sp-hero">
      <div className="sp-hero-grid">
        <div className="sp-hero-text">
          <div className="eyebrow">PhD · Computing Science · University of Alberta</div>
          <h1 className="sp-display">
            Katyani<br />
            <em>Singh</em>
          </h1>
         <p className="sp-tag">
  Building trustworthy multimodal AI through optimization and representation learning.
</p>

<div className="sp-bio">
  <p>
    I'm a PhD researcher in Computing Science at the
    <a href="https://ualberta.ca" target="_blank" rel="noopener"> University of Alberta</a> and the
    <a href="https://www.amii.ca/" target="_blank" rel="noopener"> Alberta Machine Intelligence Institute (Amii)</a>,
    advised by
    <a href="https://webdocs.cs.ualberta.ca/~nidhih/" target="_blank" rel="noopener"> Dr. Nidhi Hegde</a>.
    My research develops the next generation of <em>trustworthy vision-language models</em> by making
    <em> fairness, robustness, and safety</em> intrinsic properties of learned representations rather than
    behaviors corrected after deployment.
  </p>

  <p>
    I bring <strong>5+ years of AI research experience</strong> across academia and industry, including
    <strong> 2 years as a Computer Vision Scientist at
    <a href="https://www.nextech3d.ai/" target="_blank" rel="noopener"> Nextech3D.ai</a></strong>,
    where I developed and deployed diffusion, vision-language, and image-to-3D systems for production-scale
    e-commerce. Previously, I completed my MSc under
    <a href="https://webdocs.cs.ualberta.ca/~nray1/" target="_blank" rel="noopener"> Dr. Nilanjan Ray</a>,
    developing an unsupervised document restoration framework that significantly improved OCR performance.
  </p>
</div>
          <div className="sp-cta-row">
            <a className="btn-primary" href="#projects">View work</a>
            <a className="btn-ghost" href="assets/Katyani_Singh_CV.pdf" download>Download CV</a>
            <a className="btn-ghost" href="#contact">Get in touch</a>
          </div>
        </div>
        <div className="sp-portrait-wrap">
          <div className="sp-portrait-frame">
            <img src="assets/katyani-portrait.jpg" alt="Katyani Singh" className="sp-portrait" />
          </div>
          <div className="sp-portrait-caption">
            <span></span>
            <span></span>
          </div>
        </div>
      </div>

     <div className="sp-quick-stats" style={{ maxWidth: '600px', margin: '5rem auto 0' }}>
  <div><div className="qs-num">5+</div><div className="qs-lbl">Years research</div></div>
  <div><div className="qs-num">2+</div><div className="qs-lbl">Years industry</div></div>
  <div><div className="qs-num">4.0</div><div className="qs-lbl">PhD GPA</div></div>
  </div>
    </section>);

}

/* ============ RESEARCH ============ */
function ResearchSection() {
  const interests = [
  'Vision-Language Models', 'AI Fairness', 'AI Safety', 'Trustworthy ML',
  'Distributionally Robust Optimization', 'Generative Models',
  'Representation Learning', 'Interpretability', 'Synthetic Data & Privacy',
  'Reinforcement Learning'];

  return (
    <section id="research" className="sp-section">
      <header className="sp-section-head">
        <div className="eyebrow">RESEARCH</div>
        <h2>Vision &amp; <em>interests</em></h2>
      </header>
      <div className="vision">
        <div className="label">Research vision</div>
        <h3>Rethinking representation: <em>fairness &amp; robustness in VLMs</em> from the ground up</h3>
        <p>
          Vision-language models are the joint backbone of multimodal AI, but they
          systematically encode and amplify the societal biases embedded in their
          web-scale training data. Existing mitigation strategies like prompt filtering,
          embedding manipulation, and sampling-time controls treat <em>symptoms</em>{' '}
          rather than causes.
        </p>
        <p>My PhD program focus is on developing a representation-centric framework that embeds fairness and distributional robustness directly into the training objectives and architectural design of VLMs. The hypothesis: biased generation corresponds to identifiable geometric structure in joint latent spaces, and this structure can be measured, regularized, and verified during training without sacrificing semantic quality or generalization.


        </p>
      </div>

      <h3 className="sp-sub">Research <em>interests</em></h3>
      <div className="interests">
        {interests.map((i) => <span key={i} className="interest">{i}</span>)}
      </div>
    </section>);

}

/* ============ PROJECTS ============ */
const SHOWCASE = [
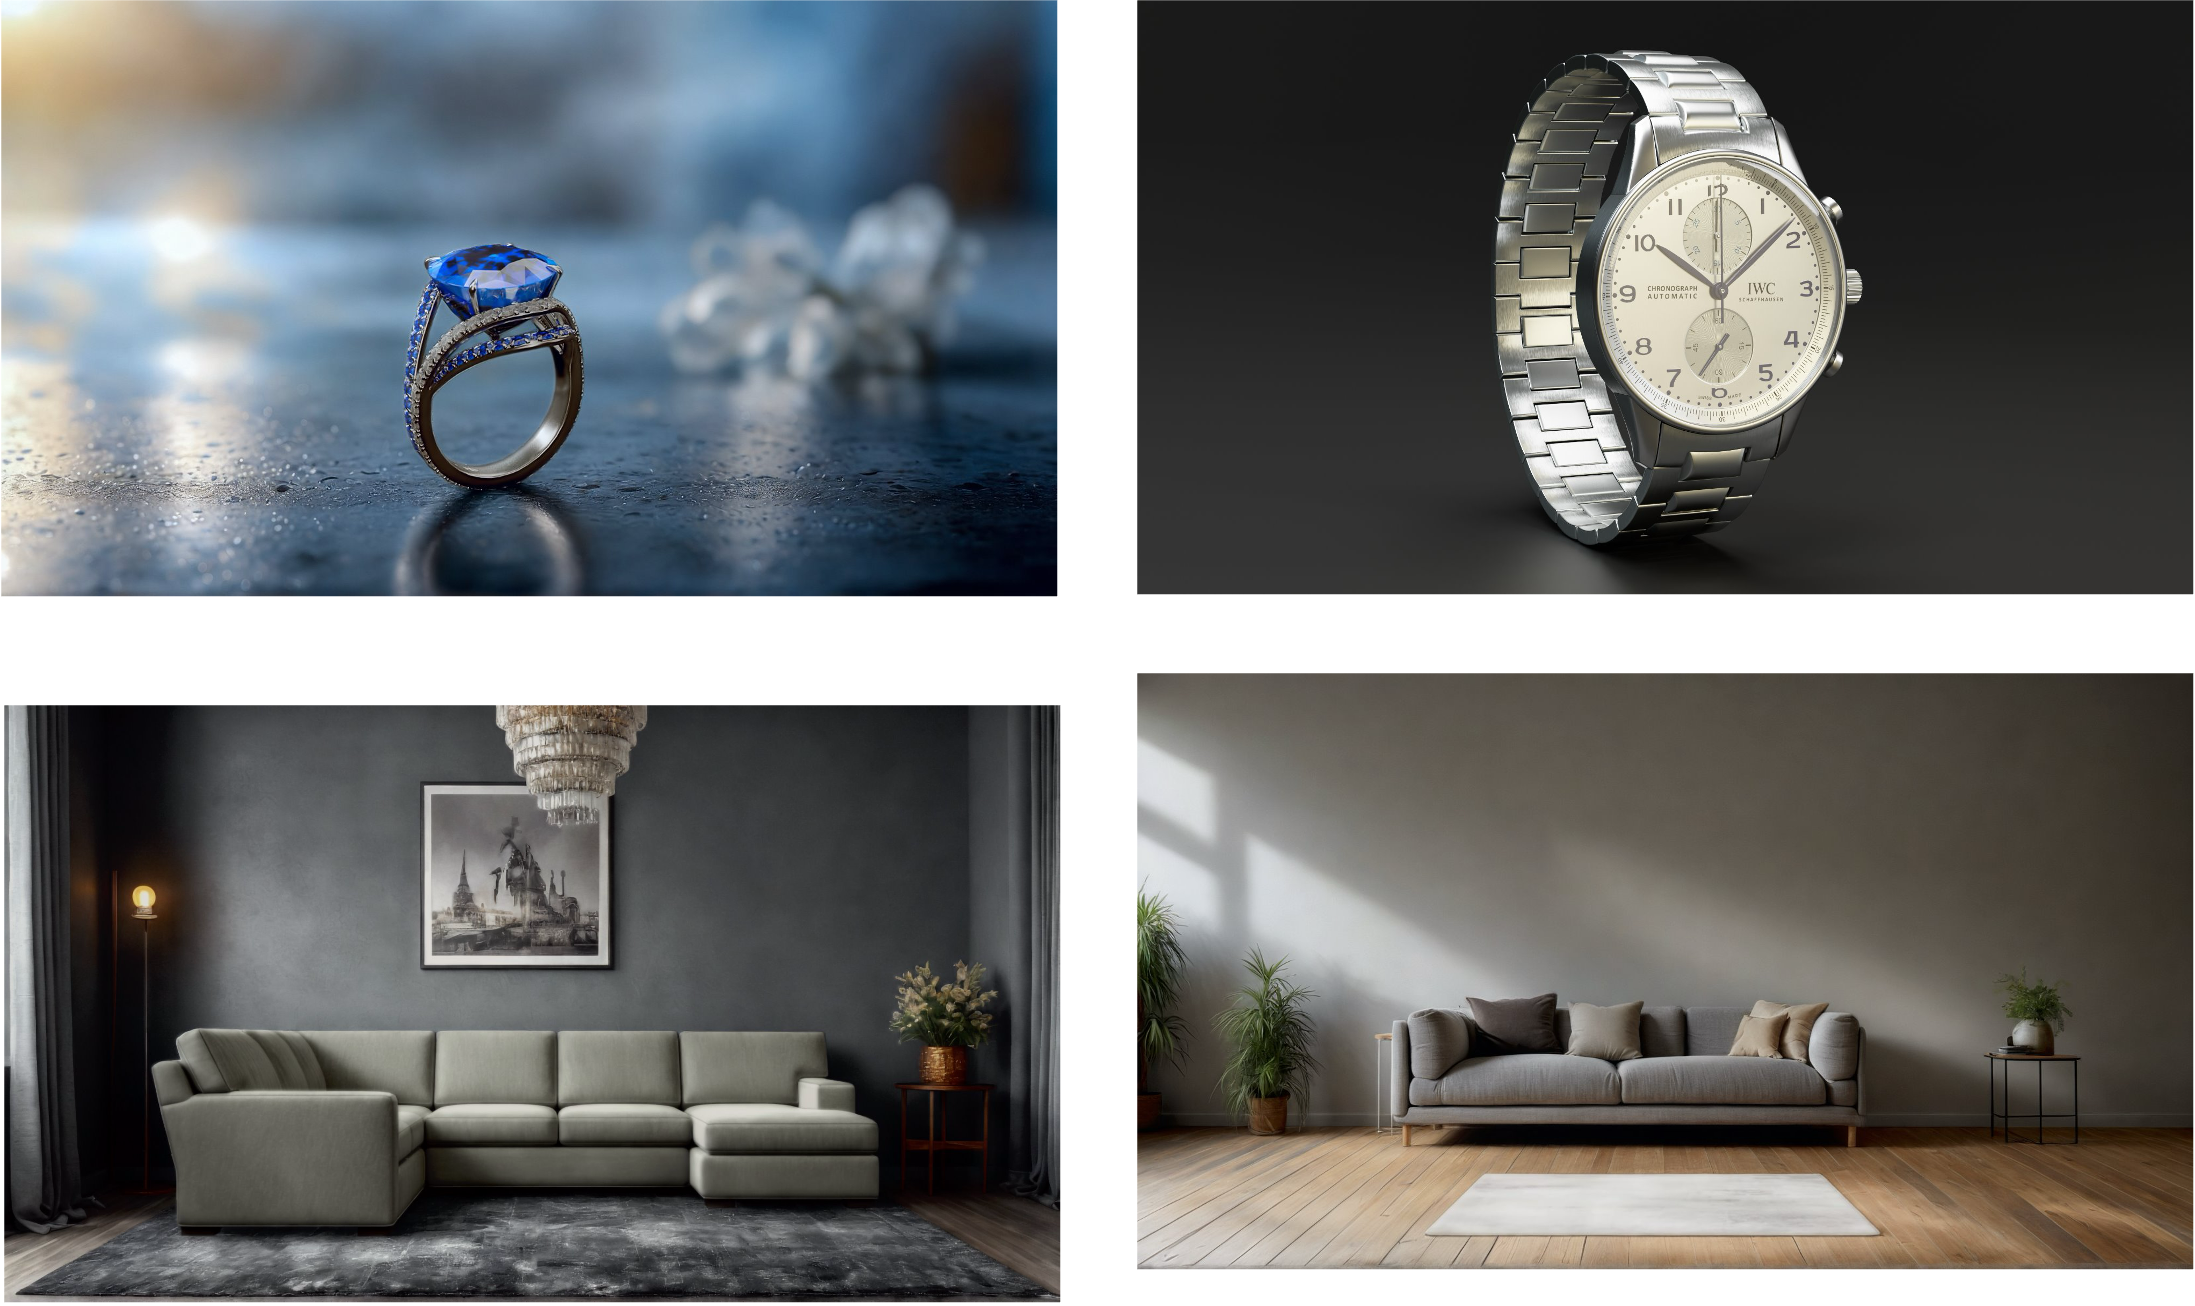
{ title: 'Lifestyle Product Photography', kind: '', tags: ['Diffusion', 'ControlNet', 'Relighting'],
  body: 'Diffusion-based virtual photography placing 3D products into stylized lifestyle scenes.',
  media: <div className="showcase-media">
      <img src="assets/lifestyle-photo.png" alt="Lifestyle product photography" />
    </div> },
{ title: 'Image-to-3D Generation', kind: '', tags: ['Fixed-Point Diffusion', '3D Recon'],
  body: 'Single product photo → editable 3D mesh via fixed-point diffusion and surface reconstruction.',
  media: <div className="showcase-media">
      <video src="assets/video-image-to-3d.mp4" autoPlay muted loop playsInline />
    </div> },
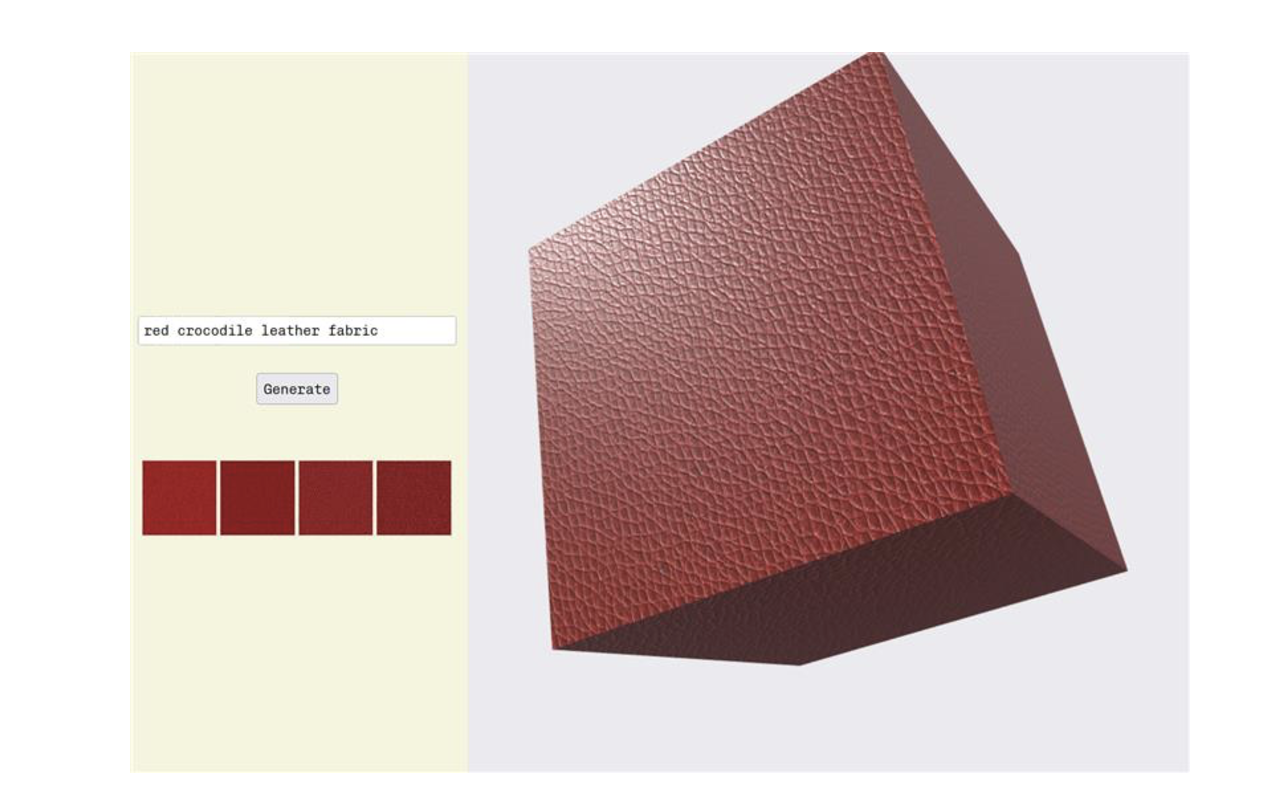
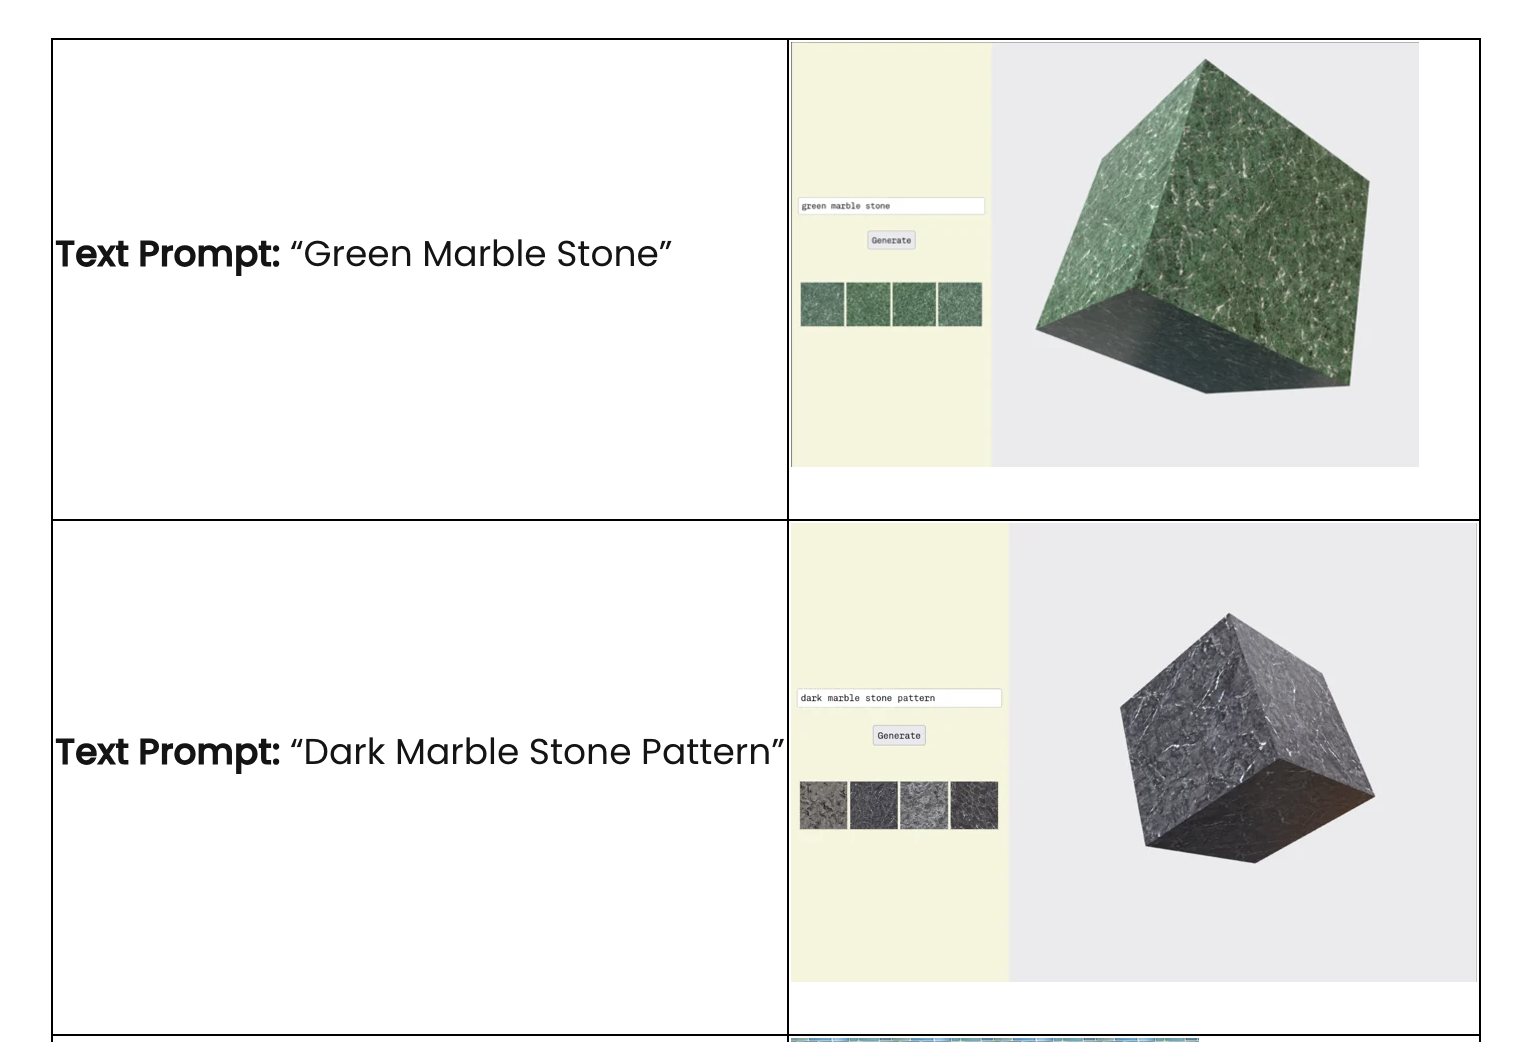
{ title: 'Text-to-Texture', kind: '', tags: ['Prompt-driven', 'PBR'],
  body: 'Prompt-driven PBR texture generation applied directly to 3D geometry.',
  media: <div className="showcase-media split contain">
      <img src="assets/portfolio-image23.png" alt="" /><img src="assets/portfolio-image24.png" alt="" />
    </div> },
{ title: 'AI Product Variation Renders', kind: '', tags: ['Variations', 'Merchandising'],
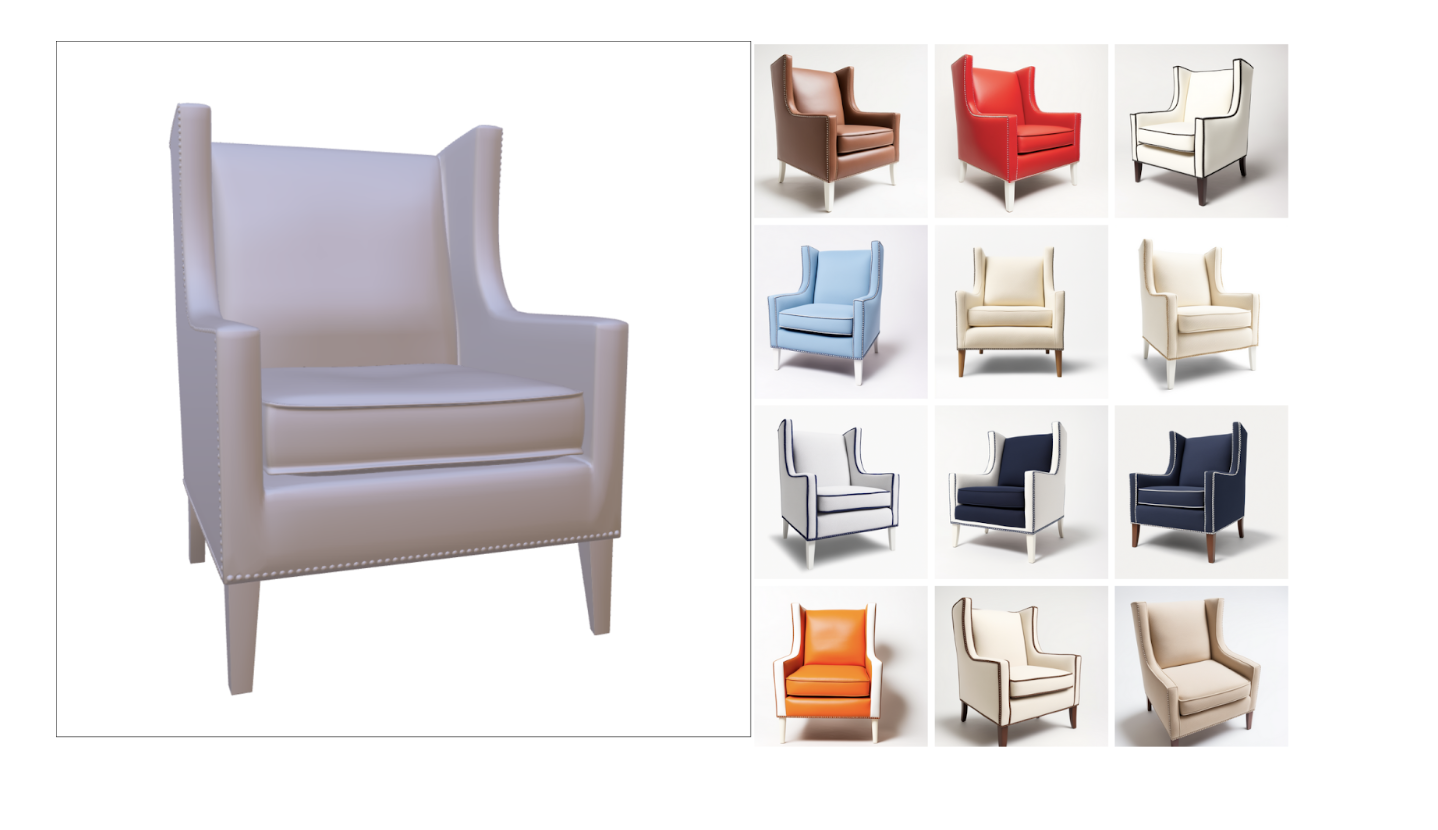
  body: 'Single 3D asset → dozens of colorways, materials, and styles.',
  media: <div className="showcase-media"><img src="assets/portfolio-image25.png" alt="" /></div> },
{ title: 'Texture Search', kind: '', tags: ['Retrieval', 'CLIP'],
  body: 'Semantic texture retrieval. Apply visually-similar materials by example or prompt.',
  media: <div className="showcase-media">
      <video src="assets/video-texture-search.mp4" autoPlay muted loop playsInline />
    </div> }];


function ProjectsSection() {
  return (
    <section id="projects" className="sp-section">
      <header className="sp-section-head">
        <div className="eyebrow">PROJECTS</div>
        <h2>Industry <em>Projects</em></h2>
        <p className="sp-section-lede">Individual and collaborative contribution.</p>
      </header>
      <div className="showcase">
        {SHOWCASE.map((p, i) =>
        <article key={i} className="showcase-card">
            {p.media}
            <div className="showcase-body">
              {p.kind ? <div className="showcase-marker">{p.kind}</div> : null}
              <h3>{p.title}</h3>
              <p>{p.body}</p>
            </div>
          </article>
        )}
      </div>

      <h3 className="sp-sub">Other <em>research</em> projects</h3>
      <div className="proj-list">
        <div className="proj-row">
          <div>
            <h4>Fairness-Aware Synthetic Healthcare Data Generation</h4>
            <p>Formulated a GAN-based framework for generating synthetic tabular healthcare data with provable fairness guarantees through multi-objective optimization. Achieved a <mark className="stat">40%</mark> reduction in demographic disparity while maintaining <mark className="stat">95%</mark> downstream task performance, establishing effective tradeoffs between utility and fairness.</p>
          </div>
        </div>
        <div className="proj-row">
          <div>
            <h4>Privacy-Utility-Fairness Tradeoffs in Synthetic Data</h4>
            <p>Systematic empirical investigation comparing Tabular GAN, CTGAN, and PATE-GAN, characterizing fundamental tradeoffs between differential privacy guarantees, utility preservation, and fairness metrics, advancing principled synthetic data generation methodologies.</p>
          </div>
        </div>
        <div className="proj-row">
          <div>
            <h4>Self-Supervised Learning for Brain MEG Signal Representation</h4>
            <p>Extended the BENDR architecture with novel pretraining objectives combining Contrastive Predictive Coding (CPC) and masked language modeling for neuroscience applications. Demonstrated a <mark className="stat">15%</mark> improvement in downstream classification tasks on limited labeled MEG data.</p>
          </div>
        </div>
      </div>
    </section>);

}

/* ============ PUBLICATIONS ============ */
function PublicationsSection() {
  return (
    <section id="publications" className="sp-section">
      <header className="sp-section-head">
        <div className="eyebrow">PUBLICATIONS</div>
        <h2>Published &amp; <em>preprint</em> work</h2>
      </header>

      <ExpandCard
        summary={<>
          <div className="pub-venue">arXiv · 2026 · Preprint</div>
          <h3 className="pub-title">RobustDebias: Debiasing Language Models using Distributionally Robust Optimization</h3>
          <div className="pub-authors">D. Gandhi, K. Singh, N. Hegde</div>
        </>}>
        <p>
          Treats fairness as a distributional invariant rather than a fixed-dataset
          statistic. Uses Distributionally Robust Optimization to reduce demographic
          bias in language models in a way that persists under distribution shift.
        </p>
        <div className="pub-tags">
          <span className="tag">LLMs</span><span className="tag">Fairness</span>
          <span className="tag">DRO</span><span className="tag">Debiasing</span>
        </div>
        <a className="pub-link" href="https://arxiv.org/abs/2602.00405" target="_blank" rel="noopener">arXiv:2602.00405 ↗</a>
      </ExpandCard>

      <ExpandCard
        summary={<>
          <div className="pub-venue">IJDAR · 2024 · Springer · 7 citations</div>
          <h3 className="pub-title">Unpaired document image denoising for OCR using BiLSTM enhanced CycleGAN</h3>
          <div className="pub-authors">K. Singh, G. Tata, E. V. Oeveren, N. Ray</div>
        </>}>
        <p>
          Unpaired image-to-image translation framework integrating a BiLSTM into
          CycleGAN for text-preserving document denoising. State-of-the-art results
          with <mark className="stat">+16.39%</mark> OCR improvement over noisy baselines
          without any paired training data. Funded by Intuit Inc. and NSERC.
        </p>
        <div className="pub-tags">
          <span className="tag">CycleGAN</span><span className="tag">BiLSTM</span>
          <span className="tag">OCR</span><span className="tag">Unpaired</span>
        </div>
        <a className="pub-link" href="https://link.springer.com/journal/10032" target="_blank" rel="noopener">International Journal on Document Analysis and Recognition (IJDAR) ↗</a>
      </ExpandCard>

      <ExpandCard
        summary={<>
          <div className="pub-venue">arXiv · 2023 · Preprint · 1 citation</div>
          <h3 className="pub-title">Document image cleaning using budget-aware black-box approximation</h3>
          <div className="pub-authors">G. Tata, K. Singh, E. Van Oeveren, N. Ray</div>
        </>}>
        <p>
          Budget-aware sample selection for OCR preprocessor training. Approximates
          a black-box OCR pipeline using a small fraction of original system queries,
          substantially reducing total training time while preserving downstream OCR
          accuracy.
        </p>
        <div className="pub-tags">
          <span className="tag">OCR</span><span className="tag">Budget-aware</span>
          <span className="tag">Black-box Approximation</span>
        </div>
        <a className="pub-link" href="https://arxiv.org/abs/2306.13236" target="_blank" rel="noopener">arXiv:2306.13236 ↗</a>
      </ExpandCard>

      <ExpandCard
        summary={<>
          <div className="pub-venue">IEEE ICSCAN · 2019 · 38 citations</div>
          <h3 className="pub-title">A comprehensive review of convolutional neural network based image enhancement techniques</h3>
          <div className="pub-authors">K. Singh, A. Seth, H. S. Sandhu, K. Samdani</div>
        </>}>
        <p>
          Survey of CNN-based image enhancement methods (denoising, super-resolution,
          deblurring, contrast and color correction), covering architectures, training
          objectives, datasets, and evaluation protocols. Published at the 2019 IEEE
          International Conference on System, Computation, Automation and Networking.
        </p>
        <div className="pub-tags">
          <span className="tag">CNNs</span><span className="tag">Image Enhancement</span>
          <span className="tag">Survey</span>
        </div>
      </ExpandCard>
    </section>);

}

/* ============ ONGOING ============ */
function OngoingSection() {
  return (
    <section id="ongoing" className="sp-section">
      <header className="sp-section-head">
        <div className="eyebrow">ONGOING PROJECTS</div>
        <h2>Research in <em>progress</em></h2>
        <p className="sp-section-lede">


        </p>
      </header>

      <ExpandCard
        summary={<>
          <div className="pub-venue">In progress · 2026</div>
          <h3 className="pub-title">Beyond Linear Debiasing: Kernel-Space Subspace Projection for VLMs</h3>
          <div className="pub-authors">K. Singh</div>
        </>}>
        
        <p>
          Post-hoc debiasing of vision-language models has relied on linear methods
          that model demographic bias as a subspace of the embedding space. This work
          (i) replicates Subspace Projection Debiasing (SPD) and Selective Feature
          Imputation (SFID) on CLIP ViT-B/32 FairFace embeddings; (ii) shows via
          MLP residual probing that substantial <em>non-linear</em> bias survives
          SPD; and (iii) introduces <strong>Kernel SPD</strong>, lifting embeddings
          into a Nyström feature space before applying the SPD pipeline.
        </p>
        <div className="pub-tags">
          <span className="tag">VLMs</span><span className="tag">Fairness</span>
          <span className="tag">Kernel Methods</span><span className="tag">CLIP</span>
          <span className="tag">Debiasing</span>
        </div>
      </ExpandCard>

      <ExpandCard
        summary={<>
          <div className="pub-venue">IN PROGRESS · 2026 </div>
          <h3 className="pub-title">Neural Ensembles for Contextual Bandits</h3>
          <div className="pub-authors">K. Singh </div>
        </>}>
        
        <p>
          Contextual bandits with neural reward models traditionally rely on costly
          gradient-based uncertainty quantification (NeuralTS, NeuralUCB). We propose
          <strong> NE-TS</strong> and <strong>NE-UCB</strong>: simpler algorithms using
          ensembles of neural networks trained via bootstrap resampling, where ensemble
          diversity itself captures epistemic uncertainty.
        </p>
        <div className="pub-tags">
          <span className="tag">Contextual Bandits</span><span className="tag">Ensembles</span>
          <span className="tag">Thompson Sampling</span><span className="tag">UCB</span>
          <span className="tag">RL</span>
        </div>
      </ExpandCard>
    </section>);

}

/* ============ INDUSTRY ============ */
function IndustrySection() {
  return (
    <section id="industry" className="sp-section">
      <header className="sp-section-head">
        <div className="eyebrow">INDUSTRY EXPERIENCE</div>
        <h2>Industry &amp; <em>internships</em></h2>
        <p className="sp-section-lede">
          Five years across computer-vision and ML roles, from research internships in India to
          shipping generative-AI vision systems at Nextech3D.ai in Canada.
        </p>
      </header>

      <div className="industry-card">
        <div className="industry-head">
          <div>
            <div className="industry-role">Machine Learning / Computer Vision Scientist</div>
            <div className="industry-company">
              <a href="https://www.nextech3d.ai/" target="_blank" rel="noopener">Nextech3D.ai</a>
              <span className="industry-meta"> · Canada</span>
            </div>
          </div>
          <div className="industry-dates">2023 to 2025</div>
        </div>
        <ul className="impact-list">
          <li><span><strong>Text-to-image virtual photography pipeline.</strong> Architected pipeline using latent diffusion models with custom relighting, achieving photorealistic 4K product integration for major retail clients (covered by <a href="https://www.theglobeandmail.com/investing/markets/markets-news/ACCESS%20Newswire/31673416/nextechs-advances-its-ai-first-initiative-with-launch-of-ecommerce-ai-studio-showcasing-humans-in-lifestyle-ai-product-photography/" target="_blank" rel="noopener">Globe and Mail / ACCESS Newswire</a>).</span></li>
          <li><span><strong>Image-to-3D reconstruction.</strong> Designed system combining diffusion priors with NeRF, enabling high-fidelity 3D asset generation from single images.</span></li>
          <li><span><strong>Multimodal retrieval for 3D assets.</strong> Built contrastive-learning retrieval systems with <mark className="stat">+35%</mark> search accuracy.</span></li>
          <li><span><strong>VLM-powered metadata generation.</strong> Deployed BLIP and InstructBLIP for automated product metadata, reducing manual annotation time by <mark className="stat">80%</mark> at <mark className="stat">92%</mark> accuracy.</span></li>
        </ul>
      </div>

      <div className="industry-card">
        <div className="industry-head">
          <div>
            <div className="industry-role">Graduate Research Assistant</div>
            <div className="industry-company">
              <a href="https://ualberta.ca" target="_blank" rel="noopener">University of Alberta</a>
              <span className="industry-meta"> · Edmonton, AB</span>
            </div>
          </div>
          <div className="industry-dates">May 2021 to Jul 2023</div>
        </div>
        <ul className="impact-list">
          <li><span><strong>Thesis: Unsupervised document image enhancement for OCR.</strong> Funded by <strong>Intuit Inc.</strong> and <strong>NSERC</strong>.</span></li>
          <li><span><strong>Unpaired image-to-image translation framework.</strong> State-of-the-art results with <mark className="stat">+16.39%</mark> OCR improvement, published in IJDAR 2024. <a href="https://era.library.ualberta.ca/items/e60d4100-a101-4dce-b250-6692e3e0508b" target="_blank" rel="noopener">Thesis link ↗</a></span></li>
        </ul>
      </div>

      <div className="industry-card">
        <div className="industry-head">
          <div>
            <div className="industry-role">Computer Vision Researcher</div>
            <div className="industry-company">
              Eigenlytics Data Solutions Pvt. Ltd.
              <span className="industry-meta"> · India</span>
            </div>
          </div>
          <div className="industry-dates">Aug to Dec 2020</div>
        </div>
        <ul className="impact-list">
          <li><span>Designed end-to-end OCR system for financial documents, achieving <mark className="stat">+28%</mark> text-localization accuracy via adaptive morphological operations and layout-aware segmentation.</span></li>
        </ul>
      </div>

      <div className="industry-card">
        <div className="industry-head">
          <div>
            <div className="industry-role">Machine Learning Researcher</div>
            <div className="industry-company">
              Ytrre Software Solutions Pvt. Ltd.
              <span className="industry-meta"> · India</span>
            </div>
          </div>
          <div className="industry-dates">May to Jun 2019</div>
        </div>
        <ul className="impact-list">
          <li><span>Developed multimodal document-understanding framework using LayoutLM-based classification, with joint visual-textual representations for automated document categorization at <mark className="stat">89%</mark> classification accuracy on heterogeneous corpora.</span></li>
        </ul>
      </div>

      <div className="industry-card">
        <div className="industry-head">
          <div>
            <div className="industry-role">Computer Vision Researcher</div>
            <div className="industry-company">
              iPing Data Labs LLP
              <span className="industry-meta"> · India</span>
            </div>
          </div>
          <div className="industry-dates">Apr 2019 to Feb 2020</div>
        </div>
        <ul className="impact-list">
          <li><span>Proposed novel defect-detection model for thermal insulation materials, achieving <mark className="stat">+32%</mark> bubble-detection accuracy via adaptive filtering.</span></li>
        </ul>
      </div>
    </section>);

}

/* ============ TEACHING ============ */
function TeachingSection() {
  return (
    <section id="teaching" className="sp-section">
      <header className="sp-section-head">
        <div className="eyebrow">TEACHING</div>
        <h2>Teaching <em>experience</em></h2>
      </header>

      <div className="ta-list">
        <div className="ta-row">
          <div className="ta-dates">Jan to Apr 2026</div>
          <div className="ta-courses">
            <div className="ta-course"><strong>CMPUT 200</strong> Ethics of Data Science and Artificial Intelligence</div>
          </div>
        </div>
        <div className="ta-row">
          <div className="ta-dates">Sep to Dec 2025</div>
          <div className="ta-courses">
            <div className="ta-course"><strong>CMPUT 566</strong> Introduction to Machine Learning</div>
          </div>
        </div>
        <div className="ta-row">
          <div className="ta-dates">Sep 2021 to May 2022</div>
          <div className="ta-courses">
            <div className="ta-course"><strong>CMPUT 175</strong> Introduction to Foundations of Computation 2</div>
            <div className="ta-course"><strong>CMPUT 101</strong> Introduction to Computing</div>
          </div>
        </div>
      </div>
    </section>);

}

/* ============ CONTACT ============ */
function ContactSection() {
  return (
    <section id="contact" className="sp-section sp-contact">
      <header className="sp-section-head">
        <div className="eyebrow">CONTACT</div>
        <h2>Get in <em>touch</em></h2>
        <p className="sp-section-lede">
          Open to research collaborations, recruiter conversations, and academic discussions.
        </p>
      </header>
      <div className="contact-grid">
        <a className="contact-card" href="mailto:katyani@ualberta.ca">
          <div className="cc-label">Email</div>
          <div className="cc-val">katyani@ualberta.ca</div>
        </a>
        <a className="contact-card" href="https://scholar.google.ca/citations?user=tVzEzkMAAAAJ&hl=en&authuser=2" target="_blank" rel="noopener">
          <div className="cc-label">Google Scholar</div>
          <div className="cc-val">View publications ↗</div>
        </a>
        <a className="contact-card" href="https://www.linkedin.com/in/katyanisingh/" target="_blank" rel="noopener">
          <div className="cc-label">LinkedIn</div>
          <div className="cc-val">Connect ↗</div>
        </a>
        <a className="contact-card" href="https://github.com/katyanisingh/" target="_blank" rel="noopener">
          <div className="cc-label">GitHub</div>
          <div className="cc-val">Code &amp; projects ↗</div>
        </a>
      </div>
      <div className="sp-foot">
        © 2026 Katyani Singh · Computing Science · University of Alberta · Edmonton, AB
      </div>
    </section>);

}

function App() {
  const active = useActiveSection();
  return (
    <>
      <StickyNav active={active} />
      <main className="sp-main">
        <AboutSection />
        <ResearchSection />
        <ProjectsSection />
        <PublicationsSection />
        <OngoingSection />
        <IndustrySection />
        <TeachingSection />
        <ContactSection />
      </main>
      <SiteTweaks />
    </>);

}

ReactDOM.createRoot(document.getElementById('root')).render(<App />);
